Depth Maps from Single Images
A depth map stores one distance per pixel, which turns a photo into a 2.5D point cloud but leaves occlusions unknown.
Why Does This Exist?
Full 3D is heavy, but many tasks need only how far each pixel sits. Stereo vision triangulates depth from two views; monocular depth estimation regresses it from one. A depth map in meters plus camera intrinsics unprojects into a point cloud, which is why detectors lift image features into bird's-eye view on top of depth. The limit is one layer: occluded backs have no pixel. The camera math underneath is image formation and camera model.
Think of It Like This
A theater seating chart with row numbers
Each seat has a row number but no note about who hides behind tall hats. You know how far every visible head sits, yet the hidden heads have no entry at all.
Pixels are seats and depth is the row. The analogy stops at scale: row numbers are exact while monocular depth needs a scale fix.
How It Actually Works
Pinhole unprojection is and , with depth , focal length and principal point . Here and are pixel coordinates, and , , are meters in camera space. Monocular networks predict inverse depth rather than directly, which balances near precision against far range during training. Error grows near-quadratically with distance because one pixel spans more meters far away.
Worked example
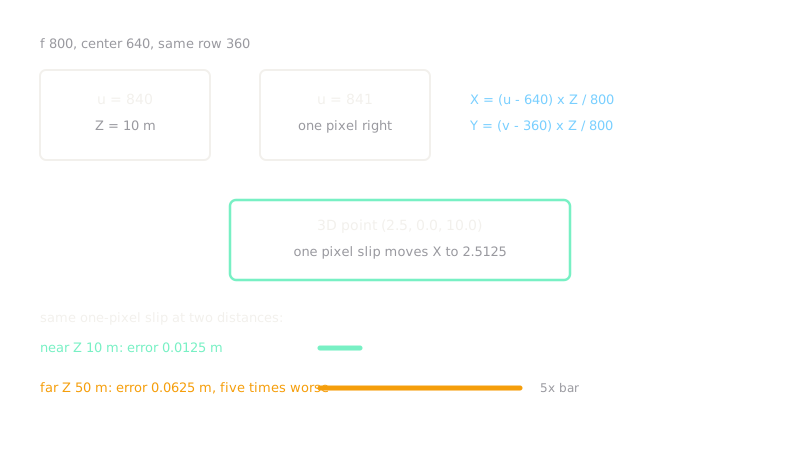
Take , , pixel and depth m. Then m and m. A one-pixel error to gives m, off by m. At m the same one-pixel slip gives m, five times worse. That growth is why far bird's-eye-view cells smear.
Code
Unprojection plus the error-growth check, printing exactly what the worked example claims.
def unproject(u: float, v: float, z: float, f: float, cx: float, cy: float) -> tuple[float, float, float]: x = (u - cx) * z / f y = (v - cy) * z / f return (x, y, z)
print(unproject(840, 360, 10.0, 800.0, 640.0, 360.0)) # -> (2.5, 0.0, 10.0)print(unproject(841, 360, 10.0, 800.0, 640.0, 360.0)) # -> (2.5125, 0.0, 10.0)print(unproject(841, 360, 50.0, 800.0, 640.0, 360.0)) # -> (12.5625, 0.0, 50.0)The last two lines differ from their exact-pixel versions by m and m: the same pixel error costs five times more at m than at m.
Watch Out For
Trusting monocular scale across cameras
One camera's m is another's m without calibration, so fused clouds split. Symptom: doubled walls in bird's-eye-view grids. Fix the scale per camera on known baselines first.
Regressing depth instead of inverse depth
Predicting directly spends most of the loss on far pixels and starves near precision. Symptom: crisp distant background with mushy nearby obstacles, the opposite of what driving needs. Fix it by predicting and converting back only at the end.
The Quick Version
- Depth maps store meters per pixel and unproject with intrinsics through .
- One pixel covers more meters far away, so the same slip costs m at m but m at m.
- Use depth when one visible layer suffices for driving or lifting to bird's-eye view.
- Do not use it for backs of objects; occlusions have no pixels.
- Predict inverse depth to balance near precision against far range.
- Monocular scale stays ambiguous per camera until calibration or stereo fixes it.