Voxels for 3D Shape Grids
Voxels put 3D shapes on a fixed grid so 3D convolutions can run, at the cost of memory that grows cubically.
Why Does This Exist?
3D sensors hand you the wrong data structure. A LiDAR sweep returns an unordered cloud of points, and a mesh is a tangle of vertices and faces, but a 3D convolution expects a plain array it can slide a kernel across. Voxels fix the mismatch by snapping space itself onto a fixed 3D grid: each cell records whether anything is there, and suddenly every 2D trick, convolution, pooling, downsampling, works in three dimensions.
The price is cubic growth. Halving the cell size multiplies the cell count by eight, so a grid fine enough to keep thin poles quickly outgrows GPU memory. This page covers voxelization, the sizing arithmetic, and the dense-versus-sparse decision that keeps voxels affordable. Raw unordered points without any grid belong to point cloud processing, and the detector that made sparse voxels famous lives under 3D object detection.
Think of It Like This
Ice cube trays for marbles
Pouring marbles into an ice cube tray sorts them into slots you can count row by row. Tiny slots keep every marble separate but you need a freezer full of trays; big slots save trays but jam two marbles into one slot and you lose track of individuals.
Voxel size is slot size and memory is freezer space. The analogy stops at emptiness: real ice trays come back full, while a voxel grid of a street comes back almost entirely empty air, which is why sparse storage matters.
How It Actually Works
From points to cells
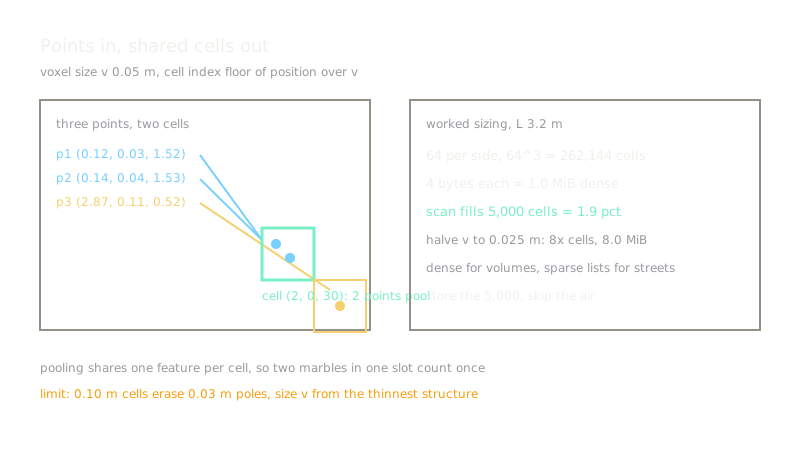
Voxelization maps a point to integer indices , where is the voxel size, the edge length of one cubic cell. Every point landing in the same cell pools into one feature, usually by averaging or max-pooling, so the cloud becomes a regular array of shape for a cubic scene of side . Dense memory follows bytes with bytes per cell, and dense 3D convolution costs grow with the same cube.
Worked sizing example
Take a street patch with side m and cells of m. Cells per side are , so the grid holds cells. At bytes each, dense storage is bytes, exactly MiB. A real scan fills only about of those cells, so occupancy is percent. Halving to m would octuple the grid to cells and MiB, which is the cubic tax made concrete.
Dense grids versus sparse lists
Below a few percent occupancy, storing the full cube wastes both memory and multiply-adds on empty air. Sparse pipelines store only occupied cells as coordinate lists and convolve only where data exists, which is exactly what detectors like SECOND exploit on LiDAR. The rule is simple: dense while occupancy is high (medical volumes, occupancy grids), sparse once air dominates (street scenes, rooms).
Code
Voxelize three points at m and count occupancy:
pts = [(0.12, 0.03, 1.52), (0.14, 0.04, 1.53), (2.87, 0.11, 0.52)]v = 0.05
vox = {}for p in pts: key = (int(p[0] // v), int(p[1] // v), int(p[2] // v)) vox.setdefault(key, []).append(p)
occ = {k: len(c) for k, c in sorted(vox.items())}print(occ, "occupied:", len(vox))# -> {(2, 0, 30): 2, (57, 2, 10): 1} occupied: 2The first two points pool into cell , the third lands alone in , and the scene that spans a index range occupies just cells.
Watch Out For
Voxel size erasing thin structures
A m voxel merges a m pole with surrounding air and the pole vanishes from every later layer. The symptom is systematic misses on poles, limbs, and wires while bulky objects detect fine. Size from the thinnest must-keep structure first, then fit memory around that choice.
Convolving densely over empty air
Running dense 3D convolution on a grid that is percent empty spends nearly all its multiply-adds on zeros and exhausts memory past on a single GPU. The symptom is out-of-memory errors on scenes that sparse baselines handle easily. Check occupancy first, and switch to sparse storage and sparse convolution whenever air dominates.
The Quick Version
- Voxels snap 3D points onto a regular grid so 3D convolution can run unchanged.
- A grid holds cells, exactly MiB at 4 bytes per cell.
- Street scans fill under percent of cells, so sparse storage keeps the occupied few thousand.
- Halving voxel size octuples memory, so size from the thinnest structure first.
- Past dense on one GPU, switch to sparse convolutions, points, or fields.