Categorical DQN (C51)
C51 predicts a full histogram over future returns instead of one average Q-value, using 51 fixed return buckets. You keep the spread and the bad tail instead of averaging them away.
Why Does This Exist?
Standard Q-learning compresses the future into one number per action:
One number hides the shape. An action that always pays +10 and a coin flip paying +100 or -80 can share the same mean, yet you would never treat them the same when hardware or money is on the line. Stochastic environments also branch into distinct modes, and averaging modes can invent a middle outcome that never happens.
Bellemare, Dabney, and Munos introduced C51 in 2017 as the first distributional agent: learn the whole return distribution instead of only its mean. The richer target steadies deep-network features because every bucket supplies gradient, not just one scalar error.
This page covers the fixed-grid mechanism: atoms, the Bellman shift, the projection back onto the grid, and the cross-entropy loss. For the mean-only baseline see deep Q-networks. For movable quantile locations instead of a fixed grid see quantile regression DQN. For C51 bundled with five other upgrades see Rainbow DQN.
You only need one prerequisite: a Q-value is the expected discounted return from a state and action, and the greedy action is the one with the highest Q.
Think of It Like This
A forecast that shows the storm, not just the average rain
You plan an outdoor wedding and ask two forecasters about rainfall.
The first says the expected rainfall is 13 mm. Useless. Is that a gentle all-day drizzle or blue skies plus a one-in-five flash flood? One number masks the danger.
The second hands you a histogram: 0 mm with 70 percent chance, 5 mm with 10 percent, 50 mm with 20 percent. Now you can compute the mean (10.5 mm) and the disaster chance (20 percent), and you rent the tent.
Map it point for point: days are episodes, rainfall amounts are returns, histogram bars are C51 atoms, and renting the tent is picking the action with the safer distribution.
Where it stops: forecasts do not change the sky. In C51 the distribution drives the action, and the Bellman update then shifts and re-projects that same distribution to train earlier states.
How It Actually Works
Let be the random return and . The distributional Bellman equation says the return equals the reward plus the discounted next return, in distribution:
where is the greedy next action picked by mean value. C51 stores each as a categorical distribution over a fixed grid.
Fixed atoms and probabilities
Pick bounds and and evenly spaced atoms:
The network outputs logits per action, and a softmax turns them into probabilities that sum to 1. The reported Q-value is the dot product:
Action selection still uses the mean. The distribution is there to train better and to expose risk.
Shift, clamp, and project
Given a transition , each atom of the next-state distribution moves:
The clipped position rarely lands on the grid, so express it in grid units:
Then split the probability across the two neighbours in proportion to closeness:
If is exactly an integer, all of lands on that atom. The vector is the projected Bellman target on the same grid.
Worked example with 5 atoms
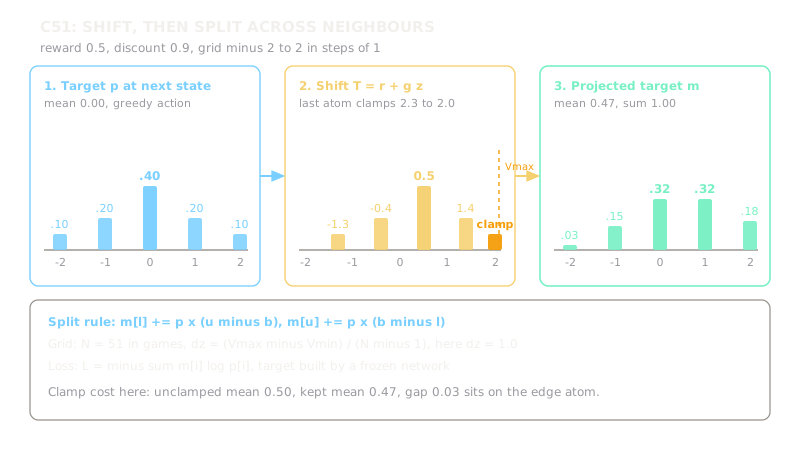
Use a small grid so every step fits on the page. Bounds and with give and atoms . Next-state probabilities at the greedy action are , whose mean is exactly . Reward and discount .
Shift each atom: . The last one exceeds , so clamp it to . In grid units that is .
Split each mass:
- Atom 0 (, ): gains , gains .
- Atom 1 (, ): gains , gains .
- Atom 2 (, ): and each gain .
- Atom 3 (, ): gains , gains .
- Atom 4 (, clamped to index 4): gains .
Totals: , which sums to . Its mean is . The unclamped math says , so the gap is the clamped tail. The diagram at the top draws these exact bars.
Why the loss is cross-entropy
Target and prediction share the grid, so training minimizes their KL divergence, which is the cross-entropy:
Use a separate target network for , as in DQN. The projection itself carries no gradient.
Code
This snippet runs the projection from the worked example with only the standard library. It prints the target masses, their sum, and their mean.
import mathfrom typing import List
def project_c51( p_next: List[float], reward: float, gamma: float, v_min: float, v_max: float,) -> List[float]: """Project a next-state distribution onto the fixed C51 support.""" n = len(p_next) dz = (v_max - v_min) / (n - 1) atoms = [v_min + i * dz for i in range(n)] m = [0.0 for _ in range(n)] for j in range(n): shifted = reward + gamma * atoms[j] clipped = min(max(shifted, v_min), v_max) b = (clipped - v_min) / dz lo = math.floor(b) hi = math.ceil(b) if lo == hi: m[lo] += p_next[j] else: m[lo] += p_next[j] * (hi - b) m[hi] += p_next[j] * (b - lo) return m
p_next = [0.10, 0.20, 0.40, 0.20, 0.10]atoms = [-2.0, -1.0, 0.0, 1.0, 2.0]m = project_c51(p_next, reward=0.5, gamma=0.9, v_min=-2.0, v_max=2.0)print([round(v, 2) for v in m])# -> [0.03, 0.15, 0.32, 0.32, 0.18]print(round(sum(m), 6))# -> 1.0mean = sum(mi * zi for mi, zi in zip(m, atoms))print(round(mean, 2))# -> 0.47Watch Out For
A support grid that cannot hold your returns
C51 clips everything outside into the edge atoms. Set the range too narrow and the whole right tail piles onto the last atom, so high-reward plans look identical and the policy undervalues them. Set it far too wide and neighbouring atoms sit dozens of points apart, so small but decisive value gaps vanish inside one bin.
Symptom: projected masses spike at an edge atom, or the agent cannot distinguish actions that differ by a few points. Fix: bracket returns from logged episodes before training, normalize rewards, and re-check the bracket when the environment changes. If you cannot bound returns at all, that is the signal to use quantile regression instead of a fixed grid.
Letting gradients flow into the projection target
The target must be treated as a constant built by the target network. If your code keeps the computation graph attached through the shift and split, gradients flow into the target and the loss chases a moving goalpost.
Symptom: loss falls but the policy oscillates or the distribution collapses toward uniform. Fix: build under no-gradient handling and confirm the optimizer only updates the online logits. The Bellman target is data, not a second prediction head.
The Quick Version
- C51 stores each action value as a categorical distribution over 51 fixed return atoms instead of one expected number.
- Q-values are the mean of that distribution, so action selection stays familiar while training sees the full shape.
- The Bellman update shifts atoms by reward plus discount, clamps them into bounds, and splits each probability across its two nearest grid neighbours.
- With atoms , reward 0.5, and discount 0.9, the worked target is with mean 0.47.
- Training minimizes cross-entropy between the projected target and the online distribution, with the target detached from gradients.